JobbyJob
A contacts spreadsheet that grew into a job search system, with an apply queue and a live voice interview coach.
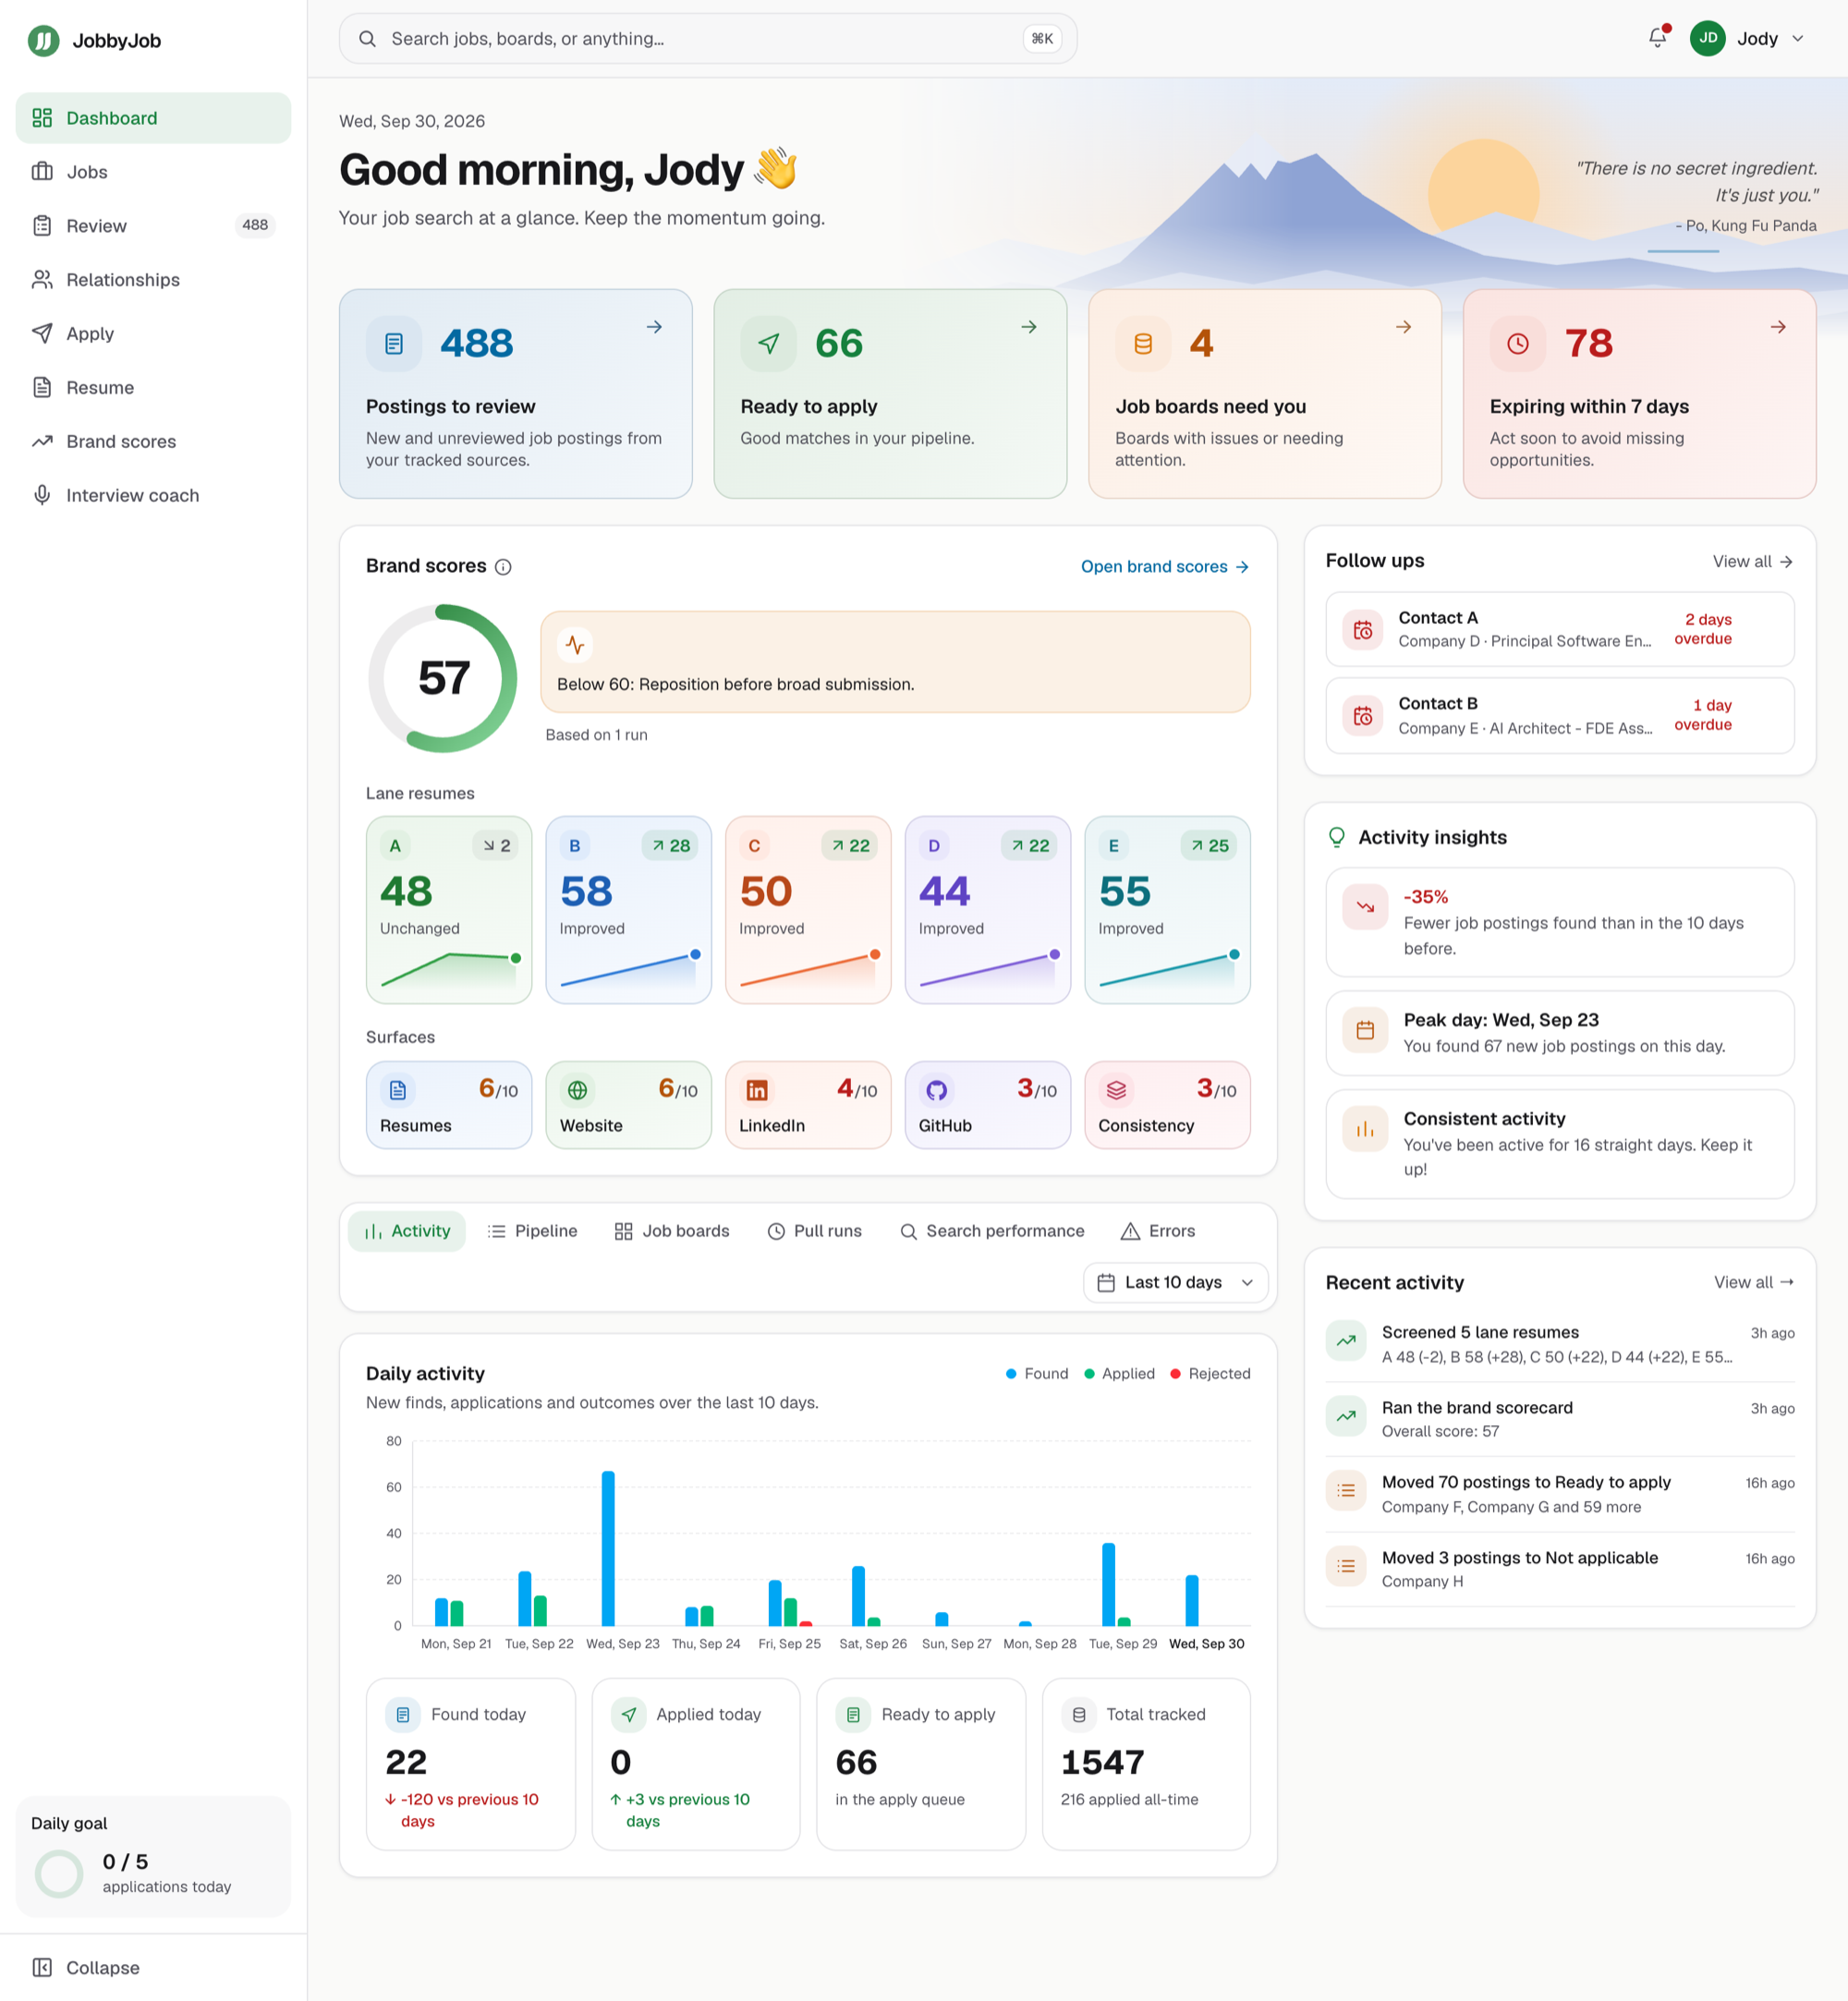 View full interface
The Challenge
A senior job search in 2026 is a volume problem that looks like a quality problem. Postings go stale in days, boards misreport remote status and posted dates, and every application wants its own resume, letter and salary answer.
The Solution
A self-hosted Teable database, extended with Claude Code, grew into a system that pulls postings overnight, scores them against my profile, tailors materials, fills forms for my review and coaches me for interviews. A model never writes a fact: code copies facts from the posting and every judgment quotes its evidence.
Architecture
A system, end to endInside the engagement
The decisions behind the work.
JobbyJob: a job search system built with Claude Code
§ 01 - context
I’m a senior engineer in South Florida going after applied AI, forward-deployed and AI product engineering roles, remote or hybrid near Miami. At the same time I was trying to learn AI engineering as it changed week to week and to relearn computer science fundamentals I hadn’t touched in years. This project became my practice ground. Every feature was a chance to try an agentic pattern on a problem with real stakes, where a bad output cost me an application instead of a demo.
§ 02 - challenge
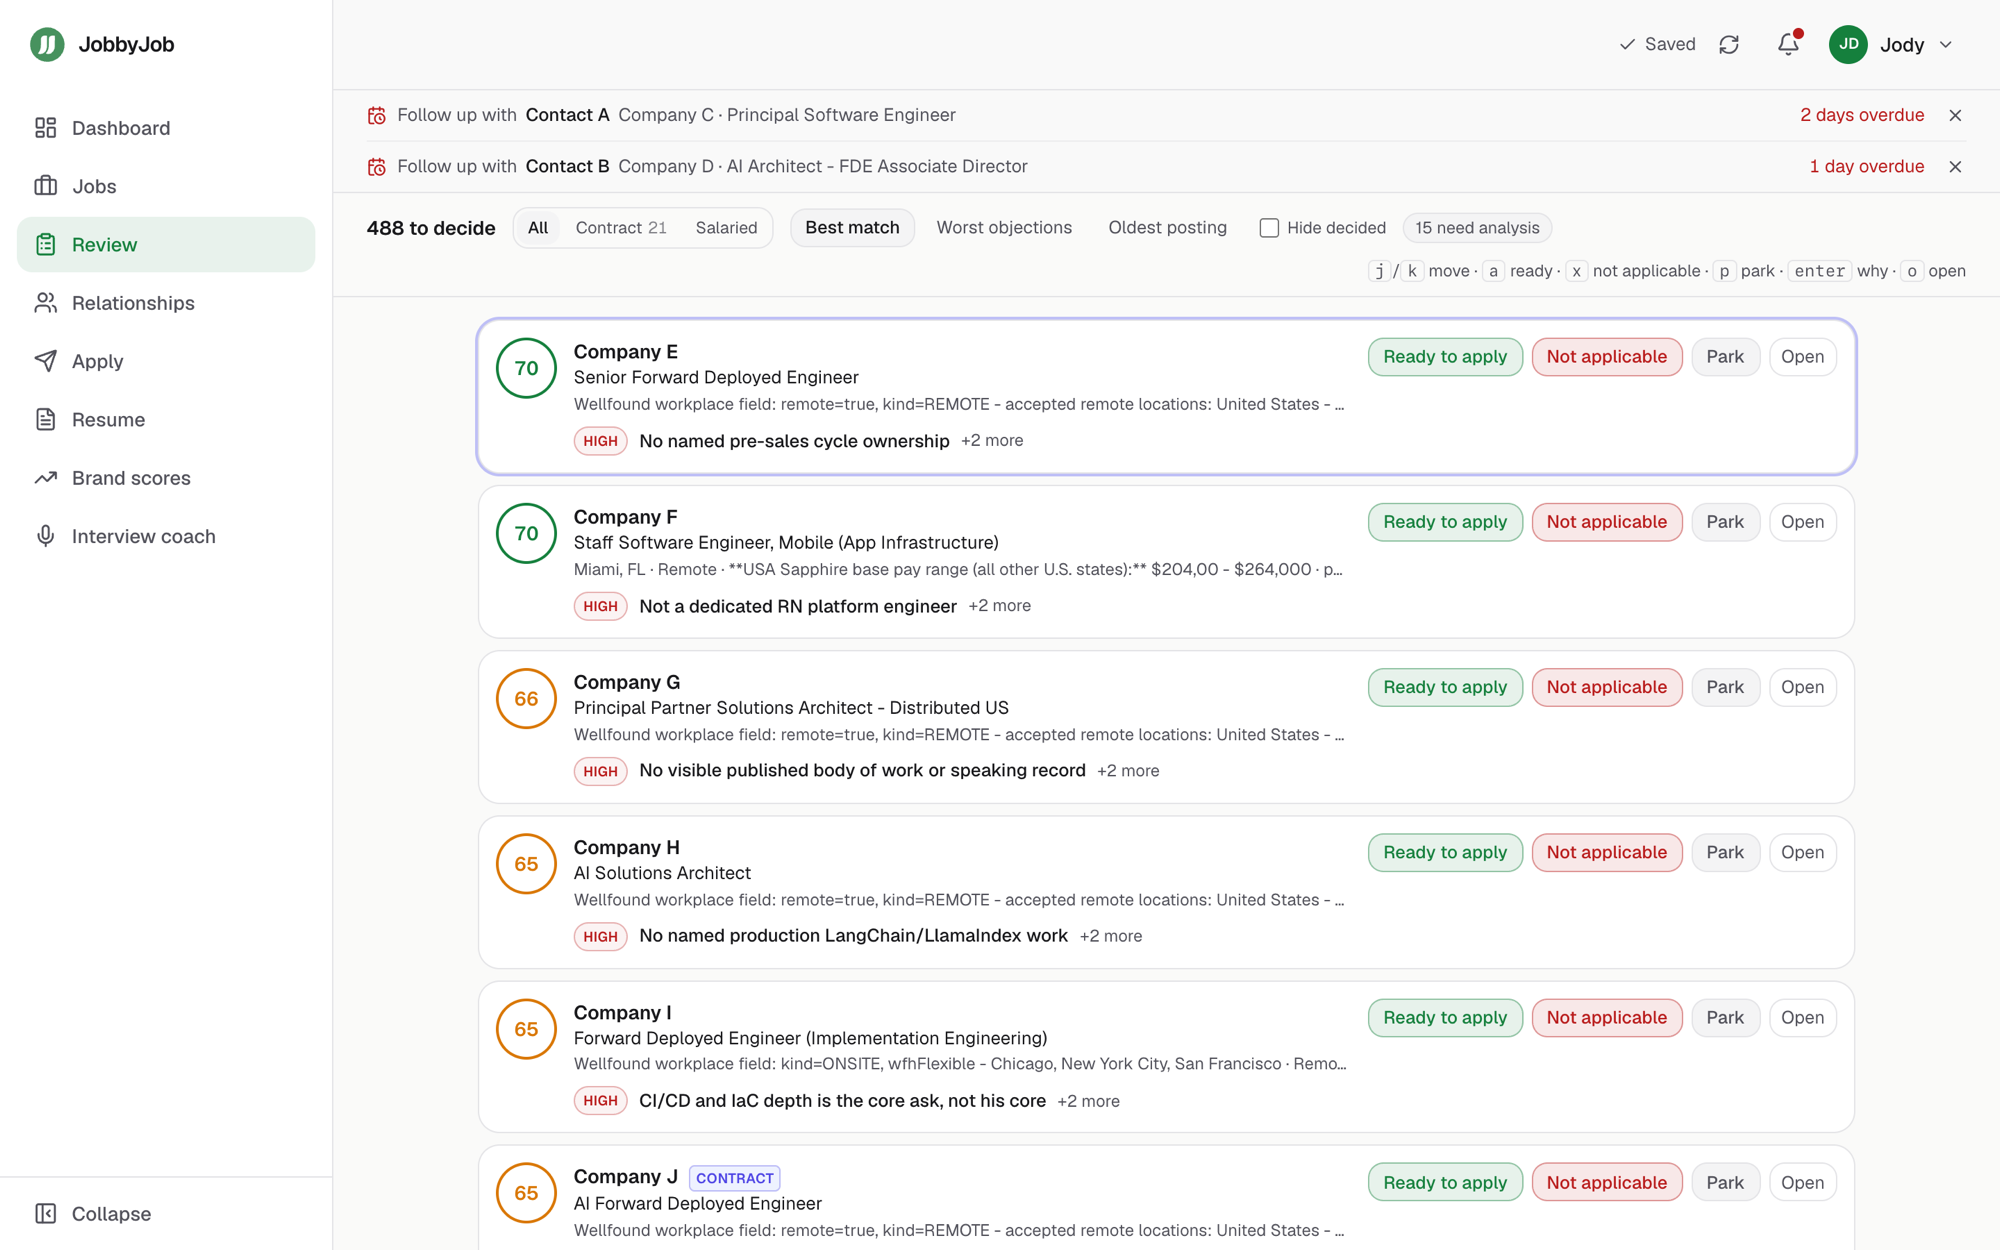
The data is wrong in small ways that add up. LinkedIn’s Remote filter returns hybrid jobs. When I checked nine LinkedIn postings against their source, eight were weeks to months older than the badge said. Indeed shows no posted date at all and hides decoy job cards in the page. Application forms ask the same twenty questions in a hundred shapes, some fields marked optional are actually required and a few make a degree mandatory.
Then there is the part no board helps with: deciding which of 1,500 postings deserve an afternoon.
§ 03 - approach
Everything ran through Claude Code. Planning and judgment stay in the main conversation. Implementation goes to subagents with a brief that names the files they own, the invariant they can’t break and the command that proves the work is done. Searches fan out to cheaper models, since they are mostly page reading at volume. Each rule lives in exactly one file (the scoring rubric, the search queries, the cover letter prompt). Prompts point at those files instead of restating them.
The hardest lesson arrived on September 18. The nightly pull was then a single agent session that read postings and typed each field into an API call by hand. Its context compacted three times that night. After the first compaction it started creating records from memory: four job URLs that existed nowhere in the fetched data, each paired with a real description from a different posting. “DO NOT MAKE UP ANYTHING” was in the prompt the whole time. An instruction to a model is not enforcement. I rebuilt the pull that day as code, with the model reduced to judgments that must quote their evidence.
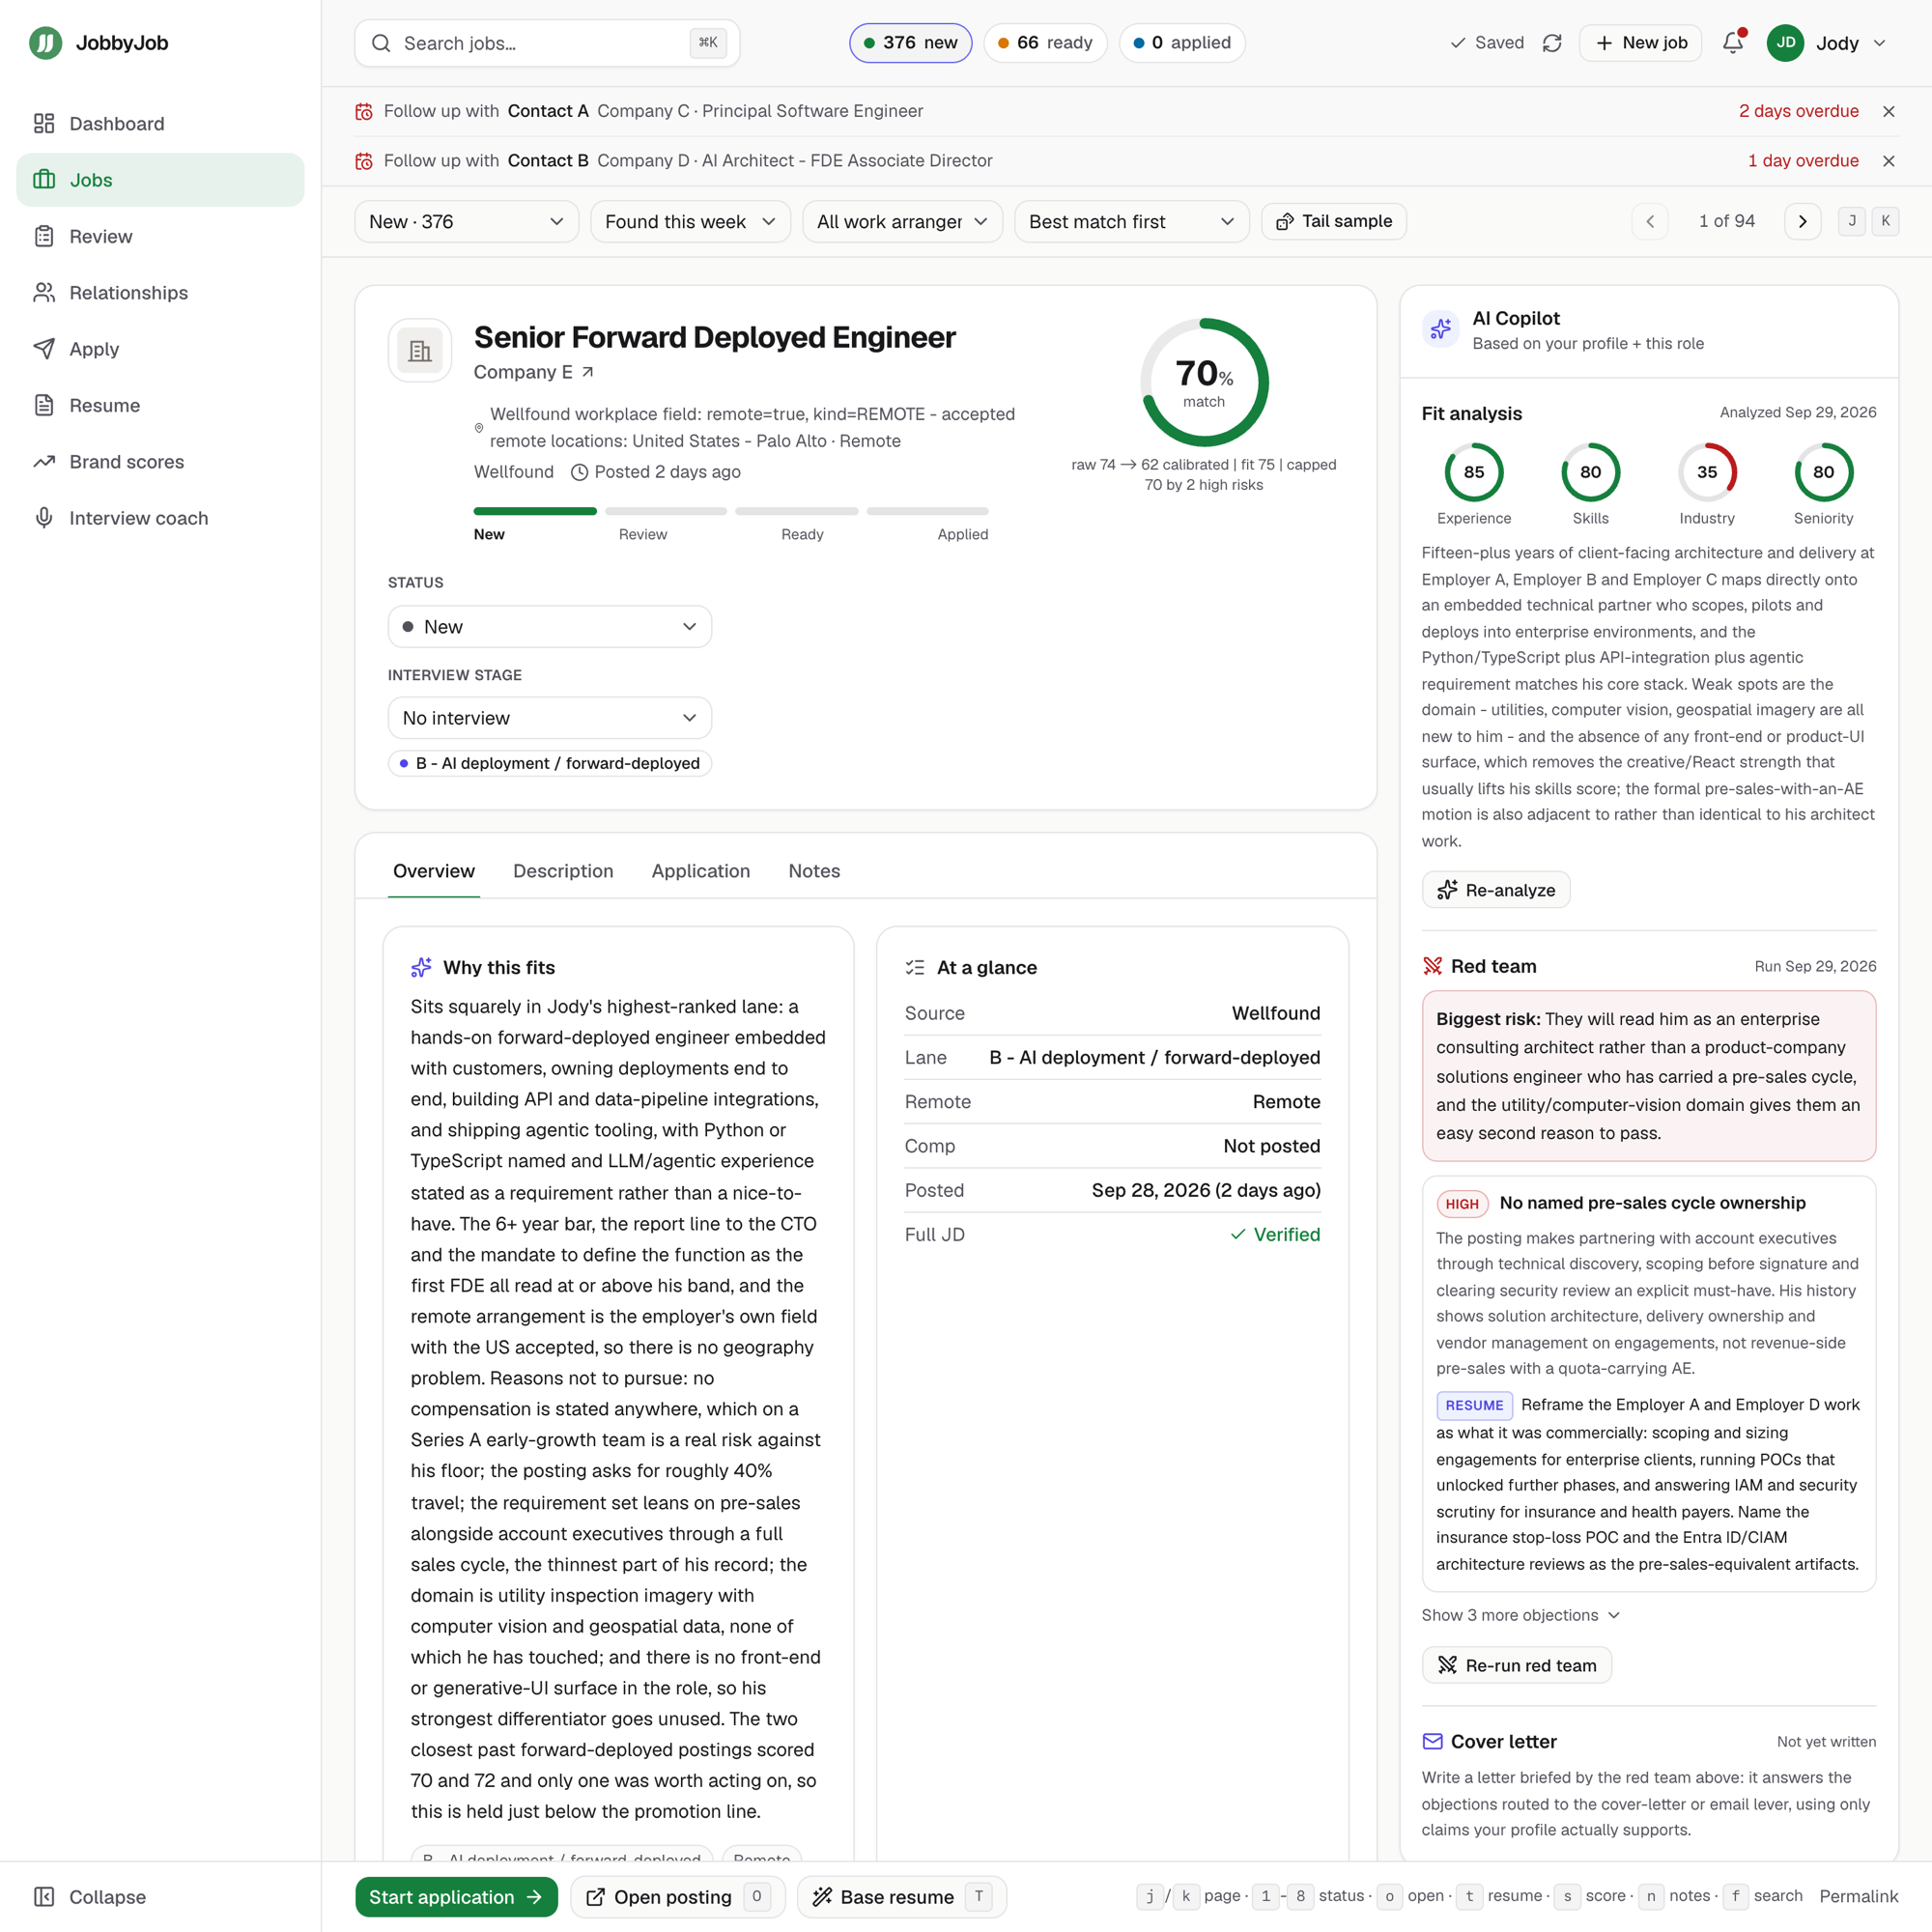
Scoring taught the same lesson a different way. The raw AI score saturated. Six of the seven jobs that ever scored 100 were ones I later marked not applicable. On average it rated jobs 36.7 points higher than I did. The number on screen is now a calibrated match that blends fit with the red-team objections. My own score stays out of the estimate because it is the thing being predicted.
The data also changed where I searched. In one late-July week, five of my eight inbound recruiter threads were for React Native or mobile work, while 38 applications to the roles I’d been targeting produced a single screen. The search reweighted around what was actually answering. It has been retargeted several times since.
§ 04 - solution
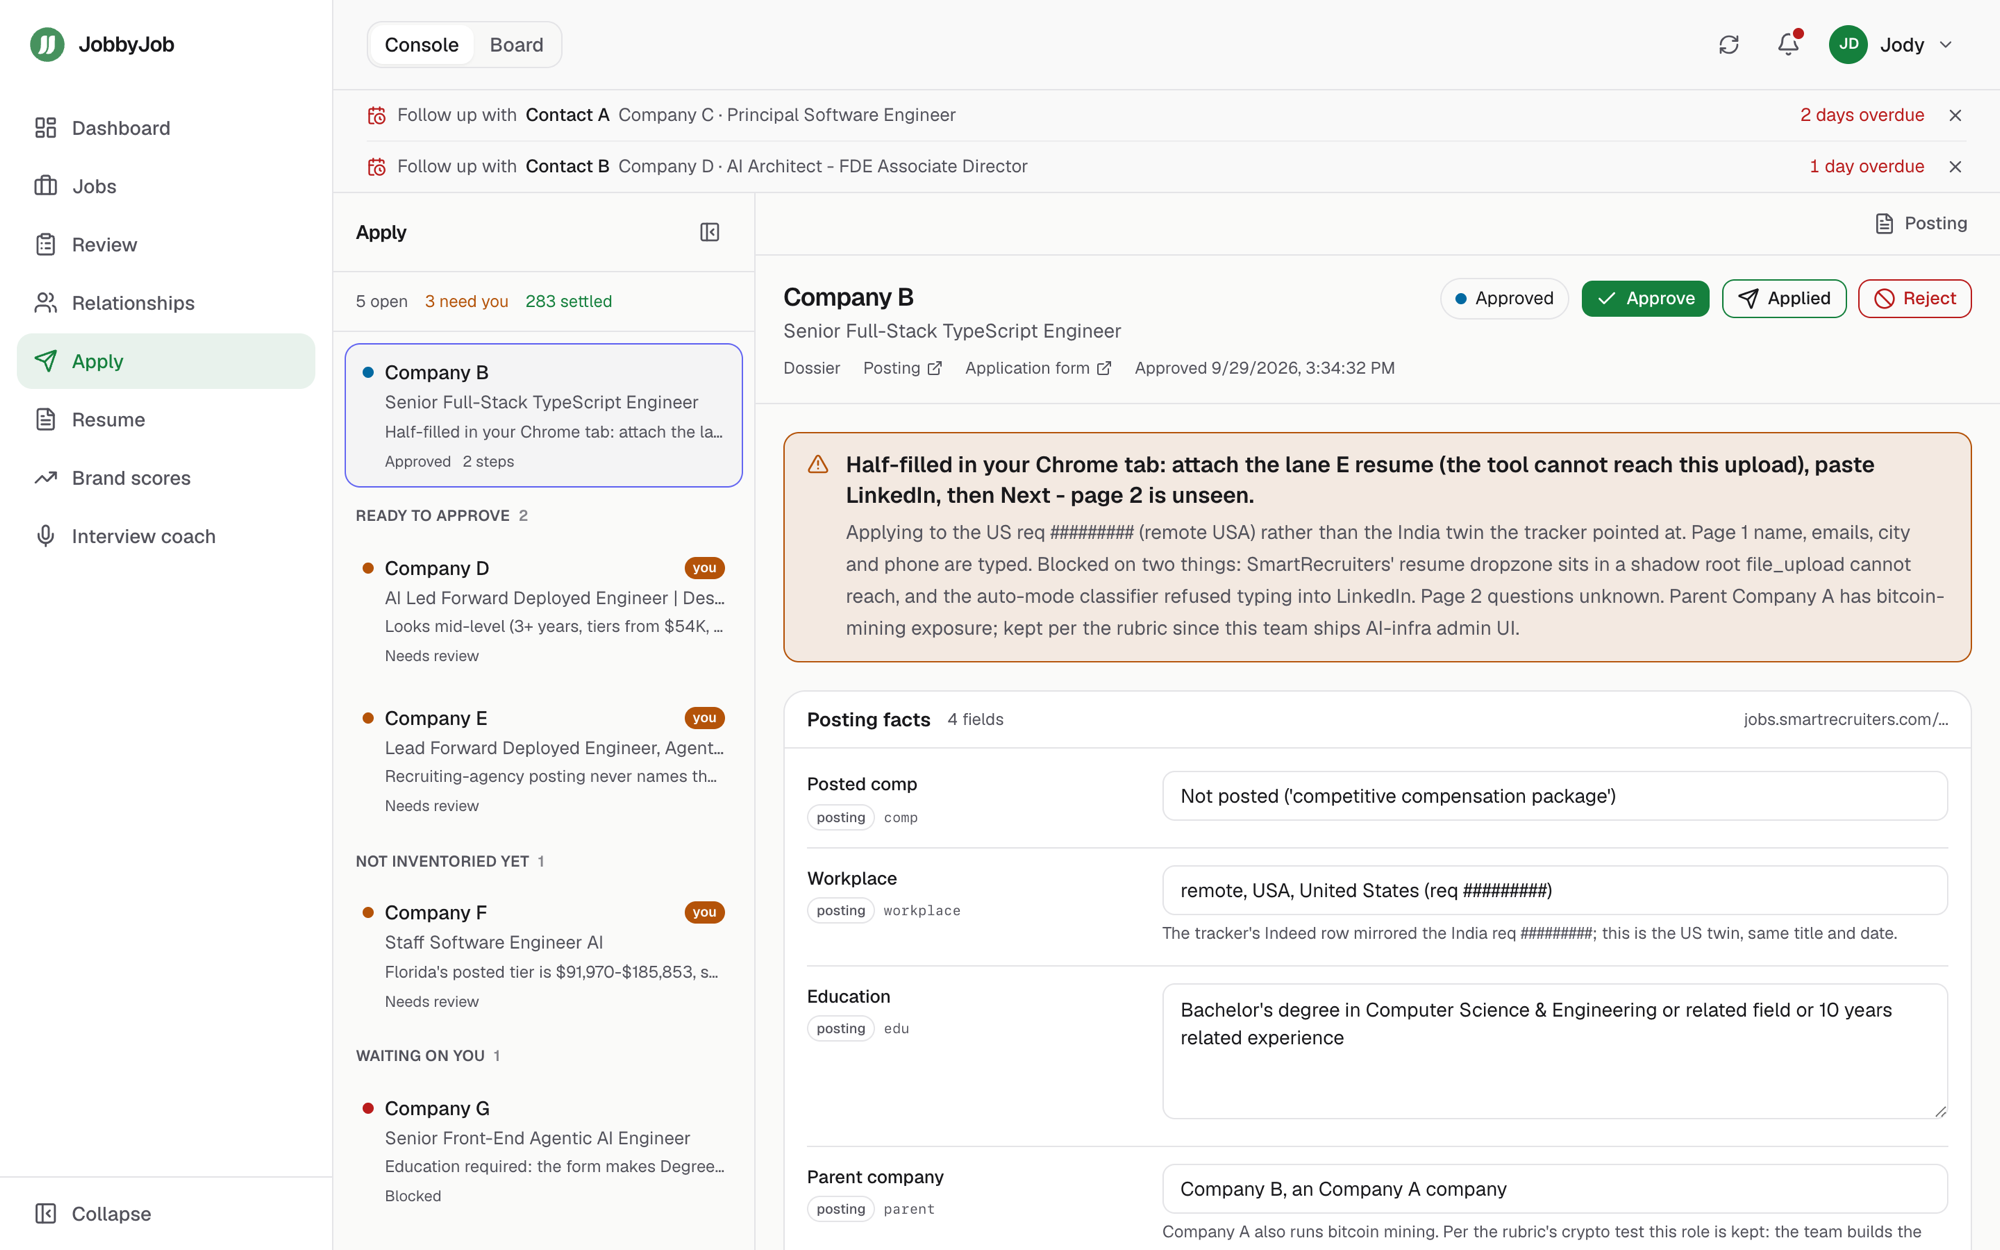
What runs today:
- A nightly pull that dedupes and drops excluded employers before scoring. It requires evidence from the posting itself for remote status, salary and location. The run fails loudly if its verification step doesn’t run.
- JobbyJob, where I triage from the keyboard: the match explanation, the gaps, a red-team card and the full posting side by side.
- Resume tailoring assembled only from bullets I’ve approved, with no model writing prose, then screened the way a lead recruiter would read it.
- /apply-ready-jobs, which works through the jobs I’ve moved to Ready to apply. It fills each form in my own browser, reads every value back out of the page before calling it filled, answers salary from the posting’s own range and parks anything unusual at Needs review with a reason.
- A Manifest V3 Chrome extension that fills the standard fields, declines every EEO question and never clicks Submit.
- A small CRM of contacts and conversations, a daily Gmail check for recruiter action items and the weekly Florida reemployment work-search report, all built from the same tracker.
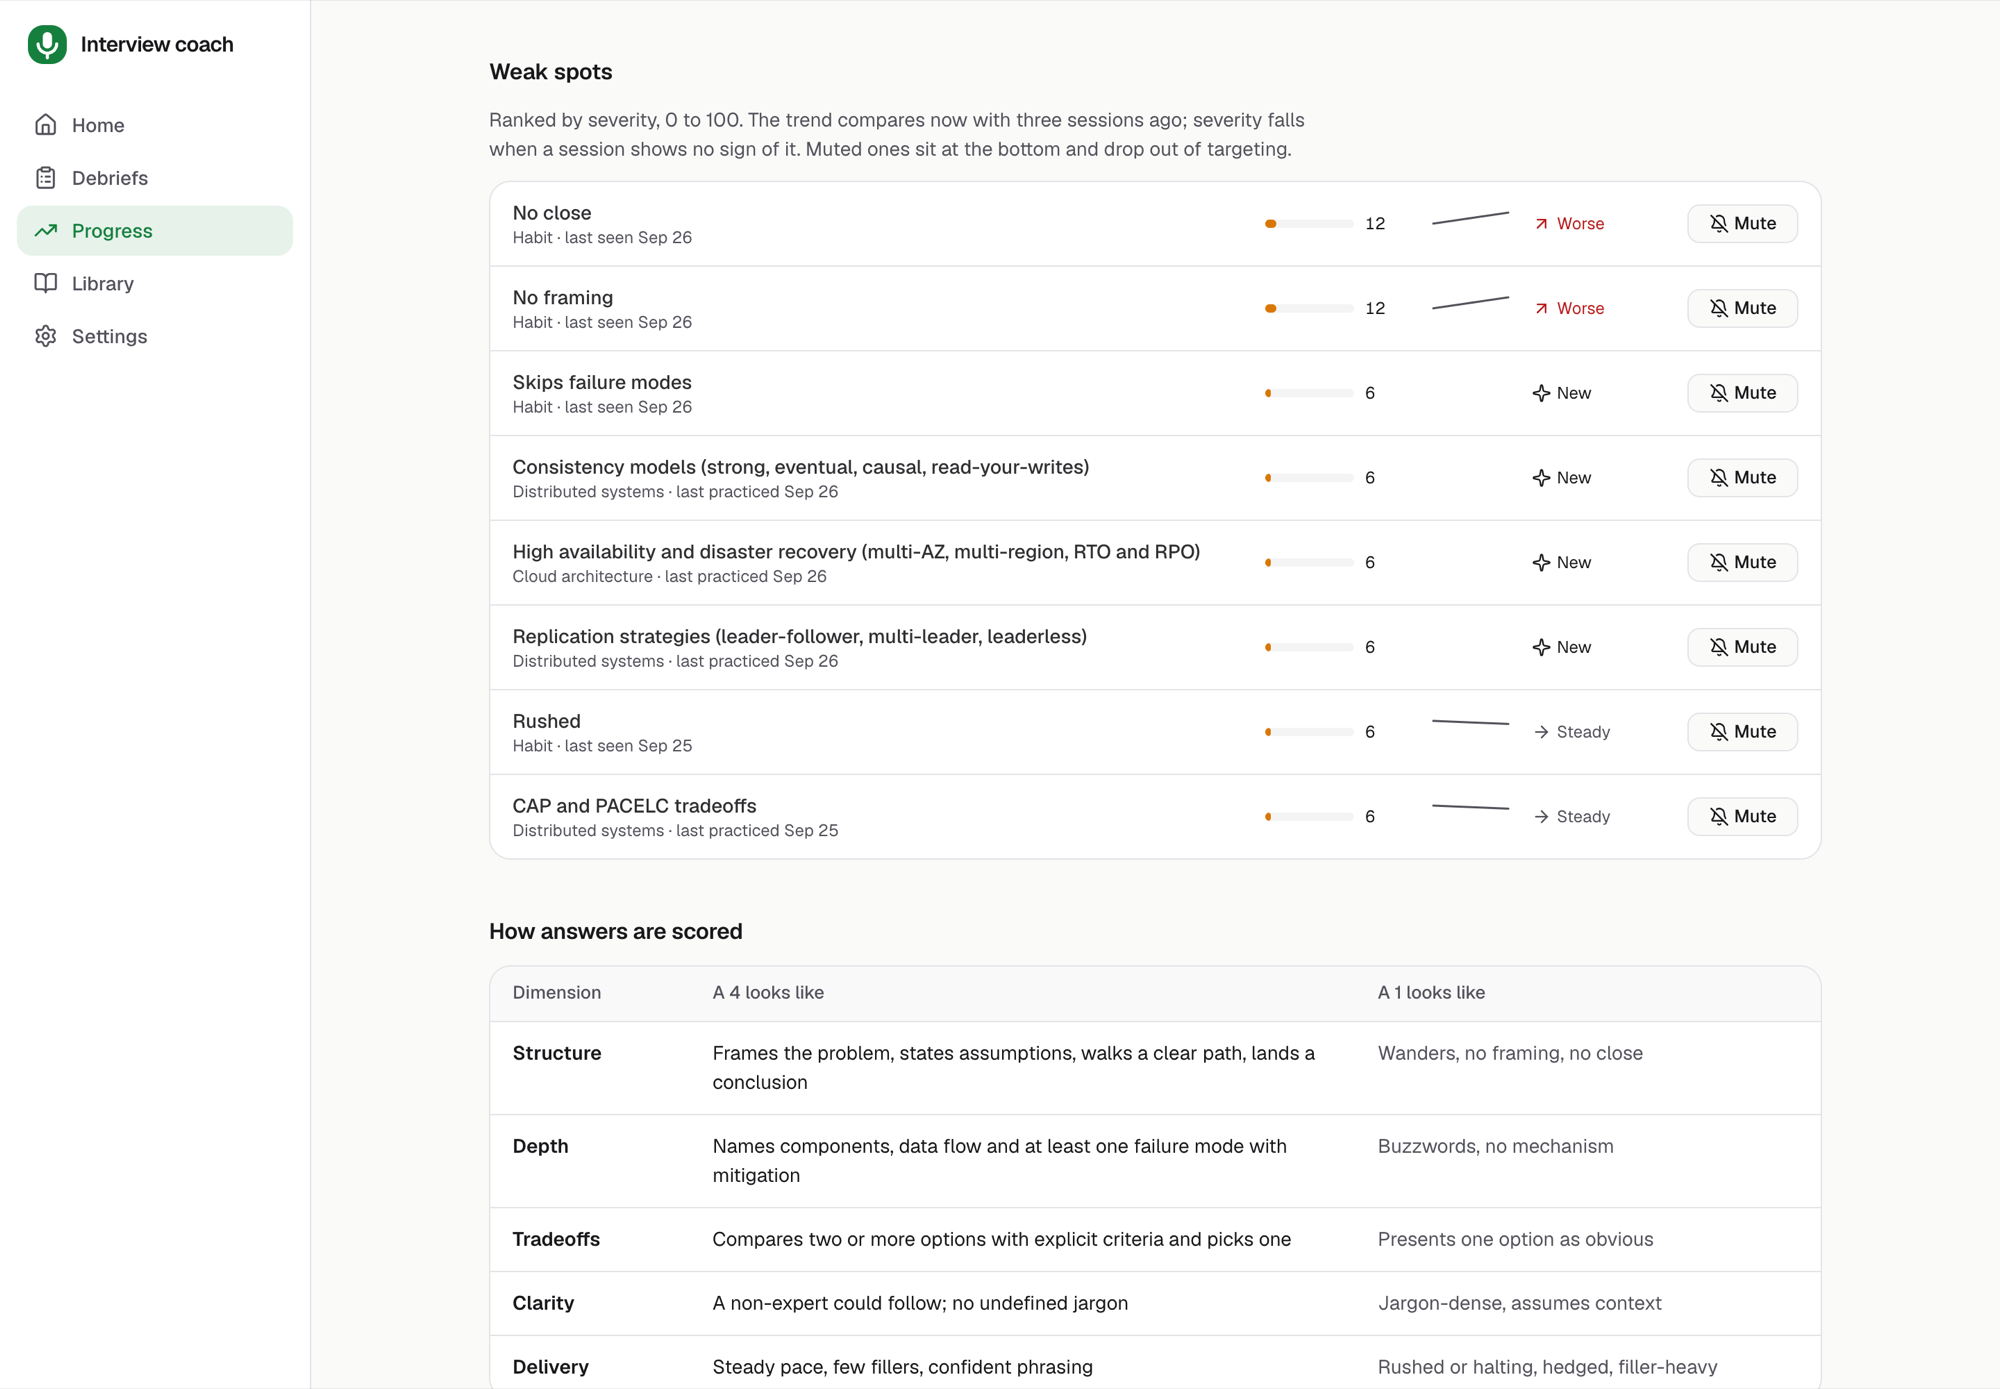
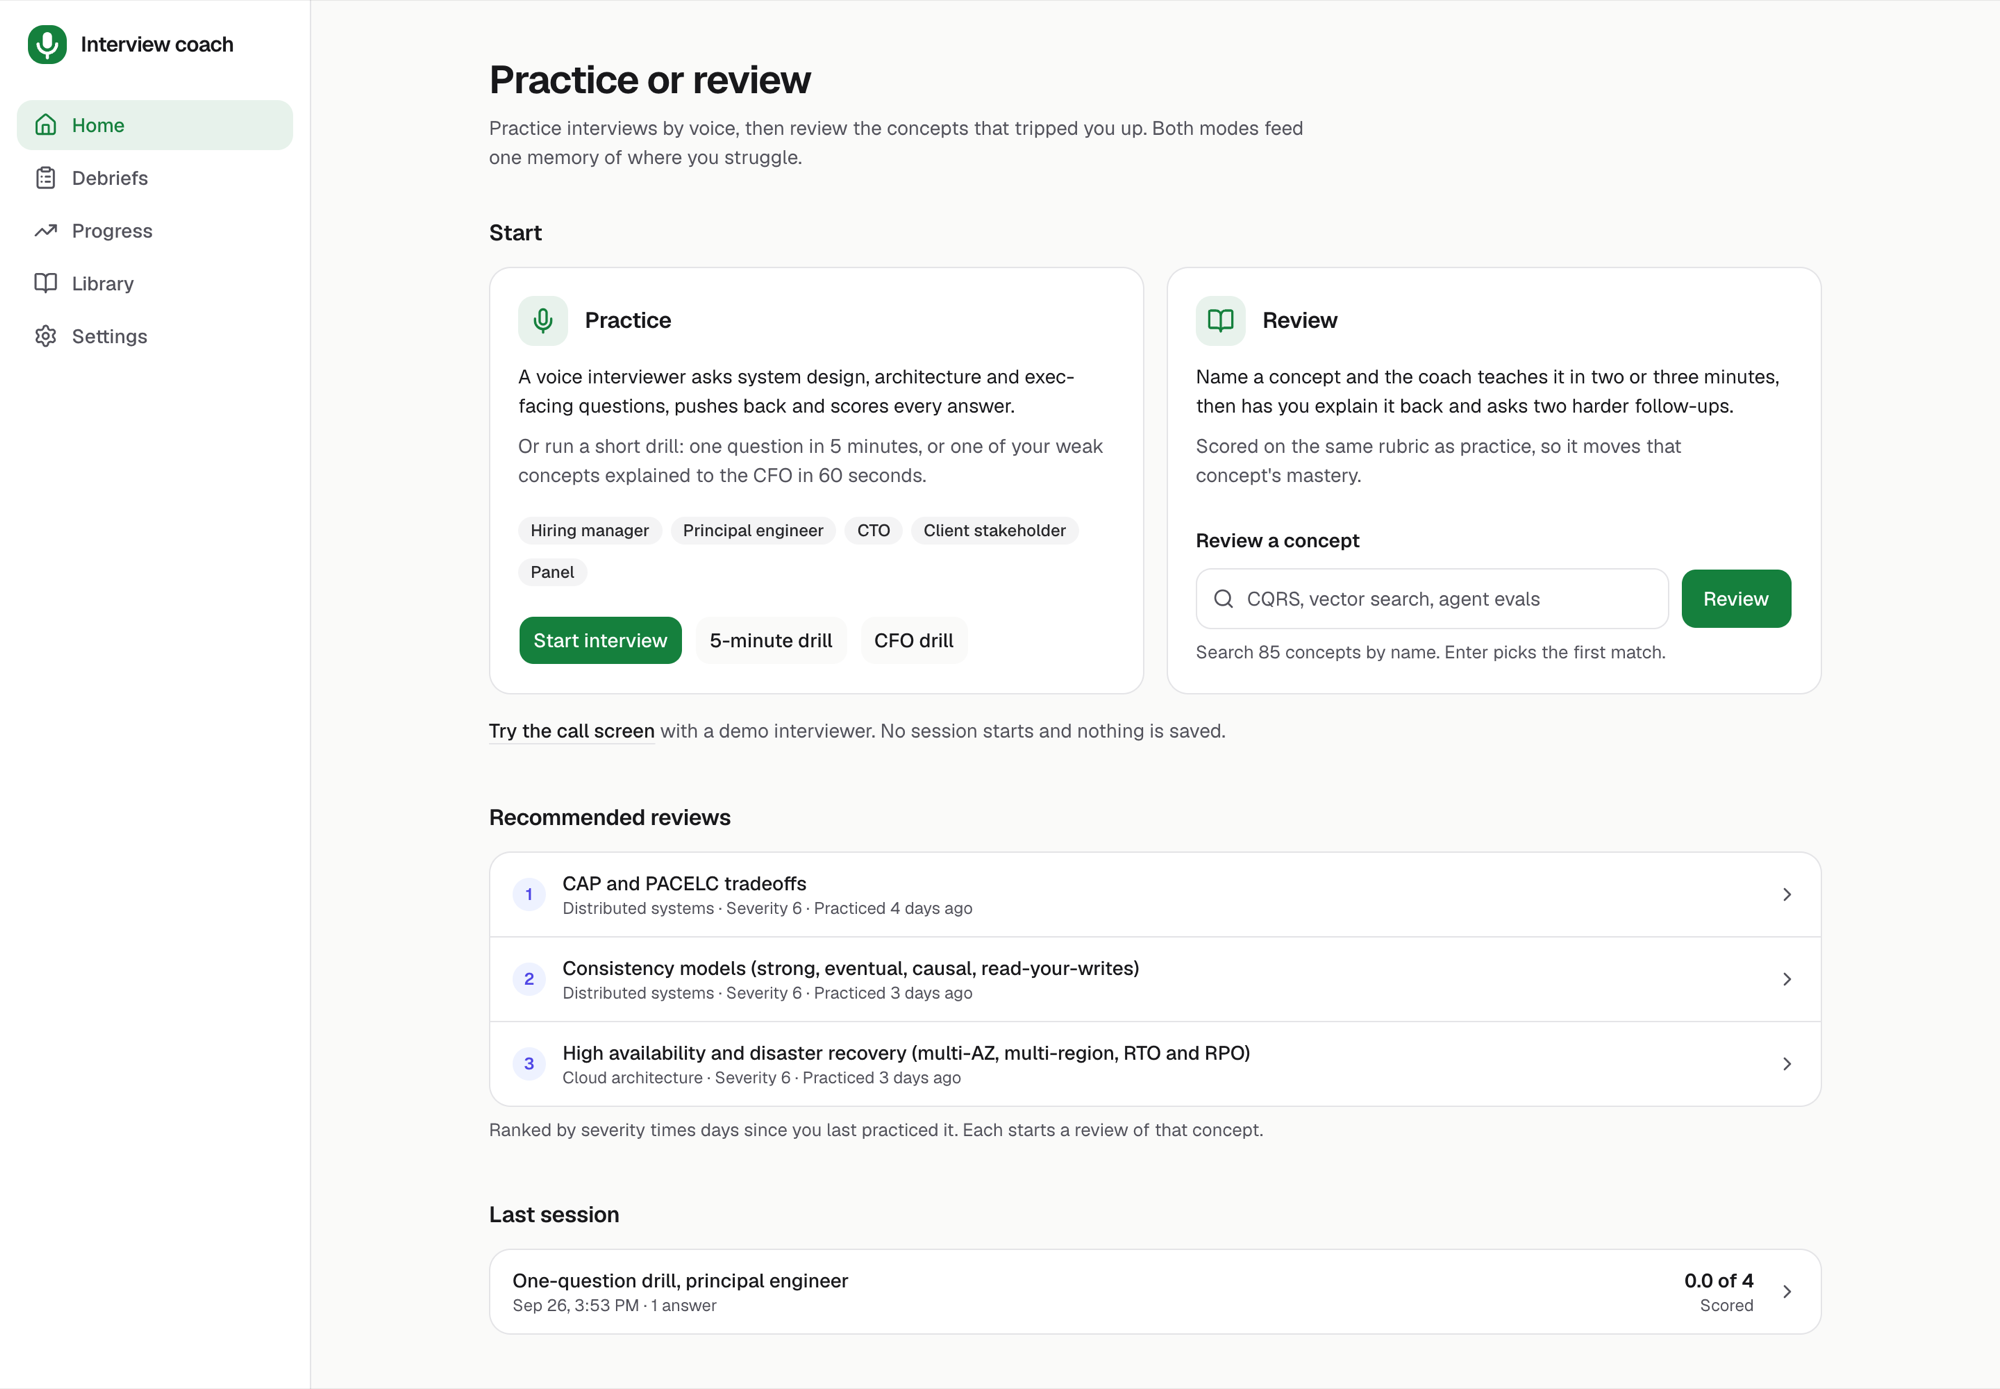
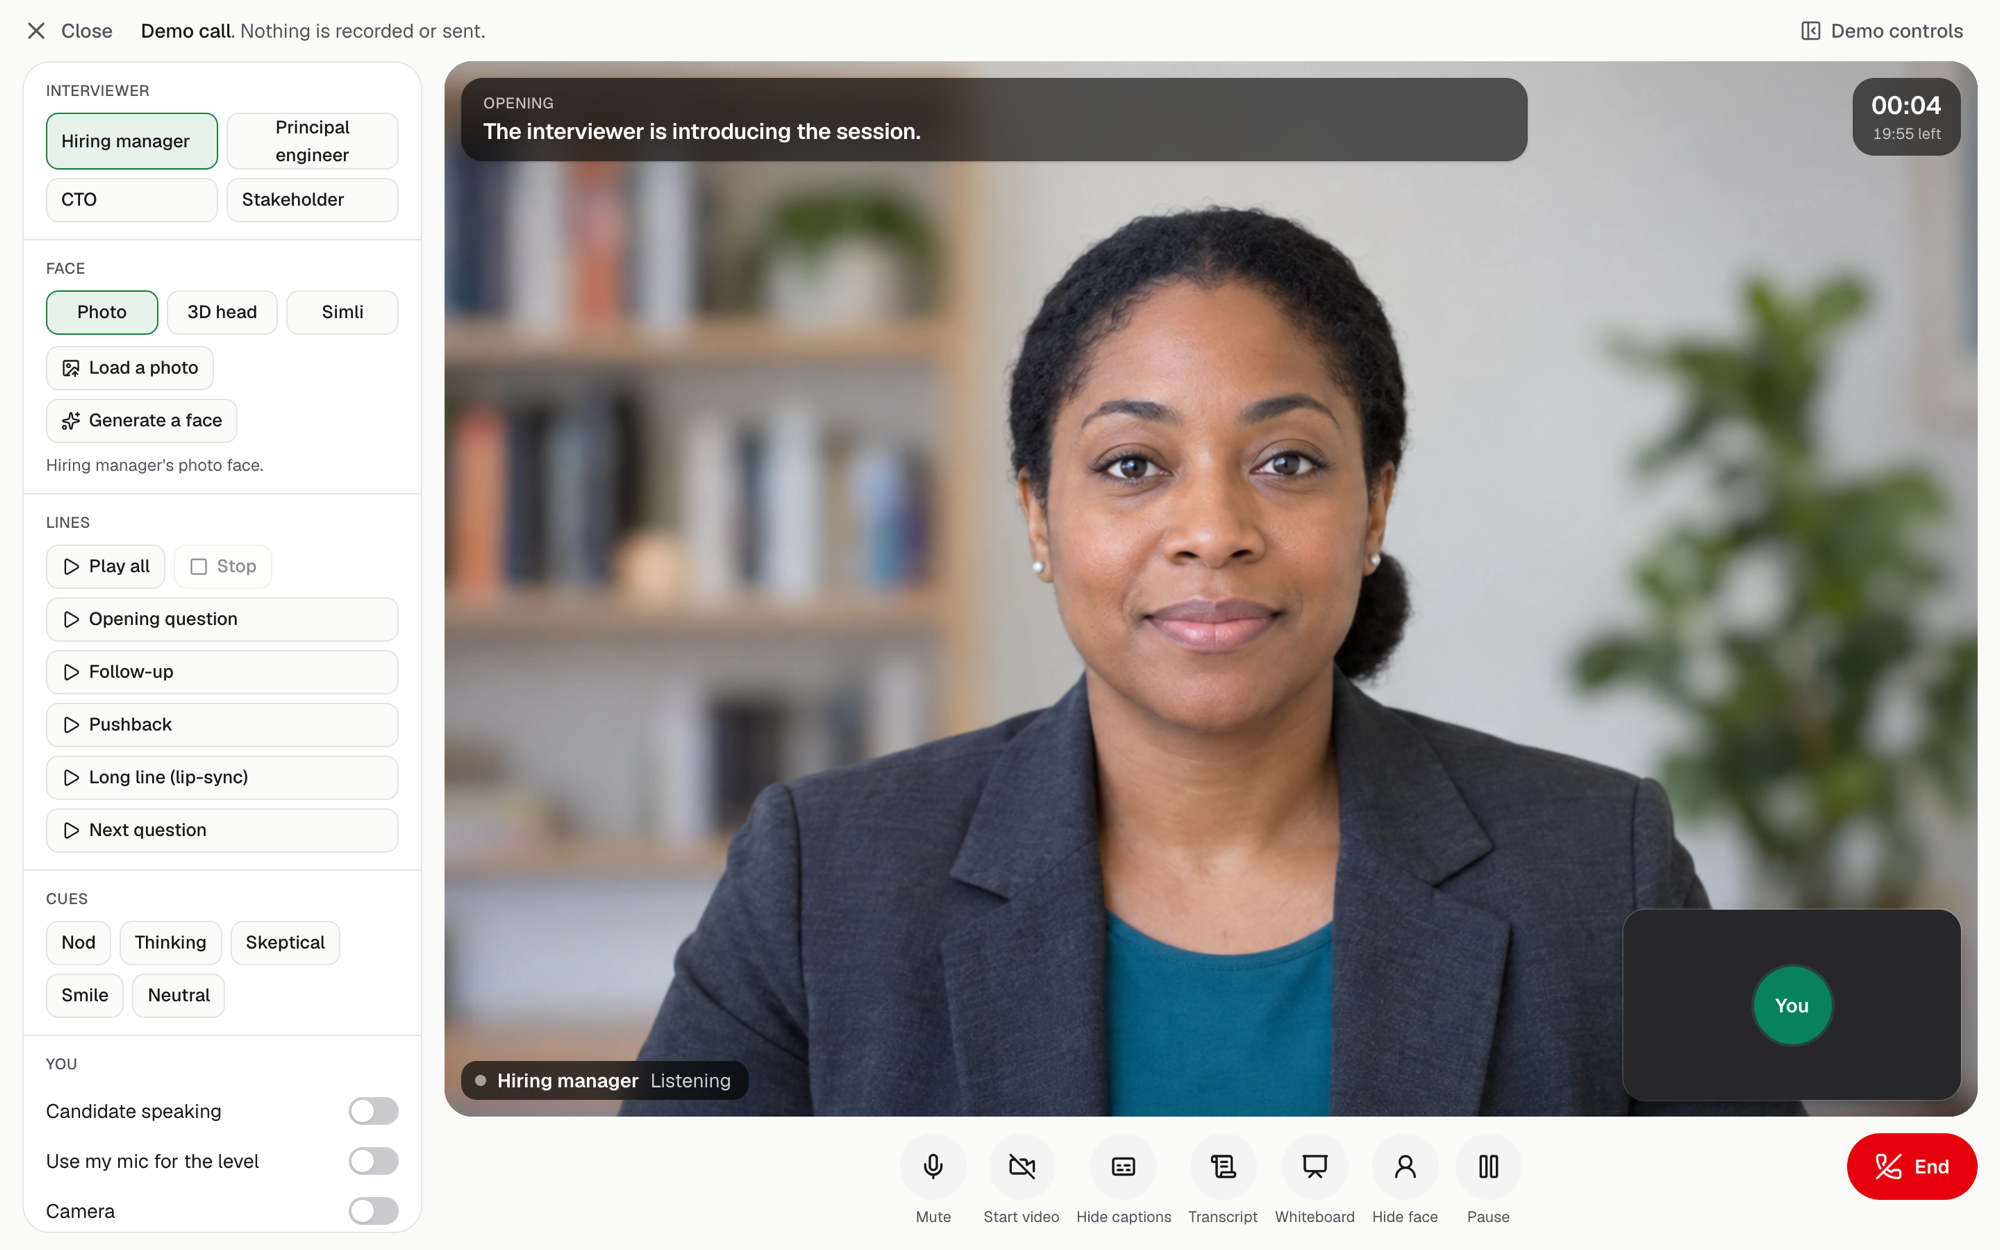
- The interview coach. A voice interviewer on OpenAI’s Realtime API, with personas that have animated faces and a whiteboard the interviewer can see. Code measures delivery from the audio (pace, filler words, pauses, hedging) and Claude scores the content against a fixed rubric. A weak-spot memory picks the next session’s questions.
§ 05 - outcomes
- 1,547 postings tracked from 7 sources
- 216 applications, each reviewed before it went out
- 18 applications in a single day, the peak
- 11 weeks from a contacts spreadsheet to a live voice coach
Recruiter screens are in progress. There is no offer yet.
§ 06 - reflection
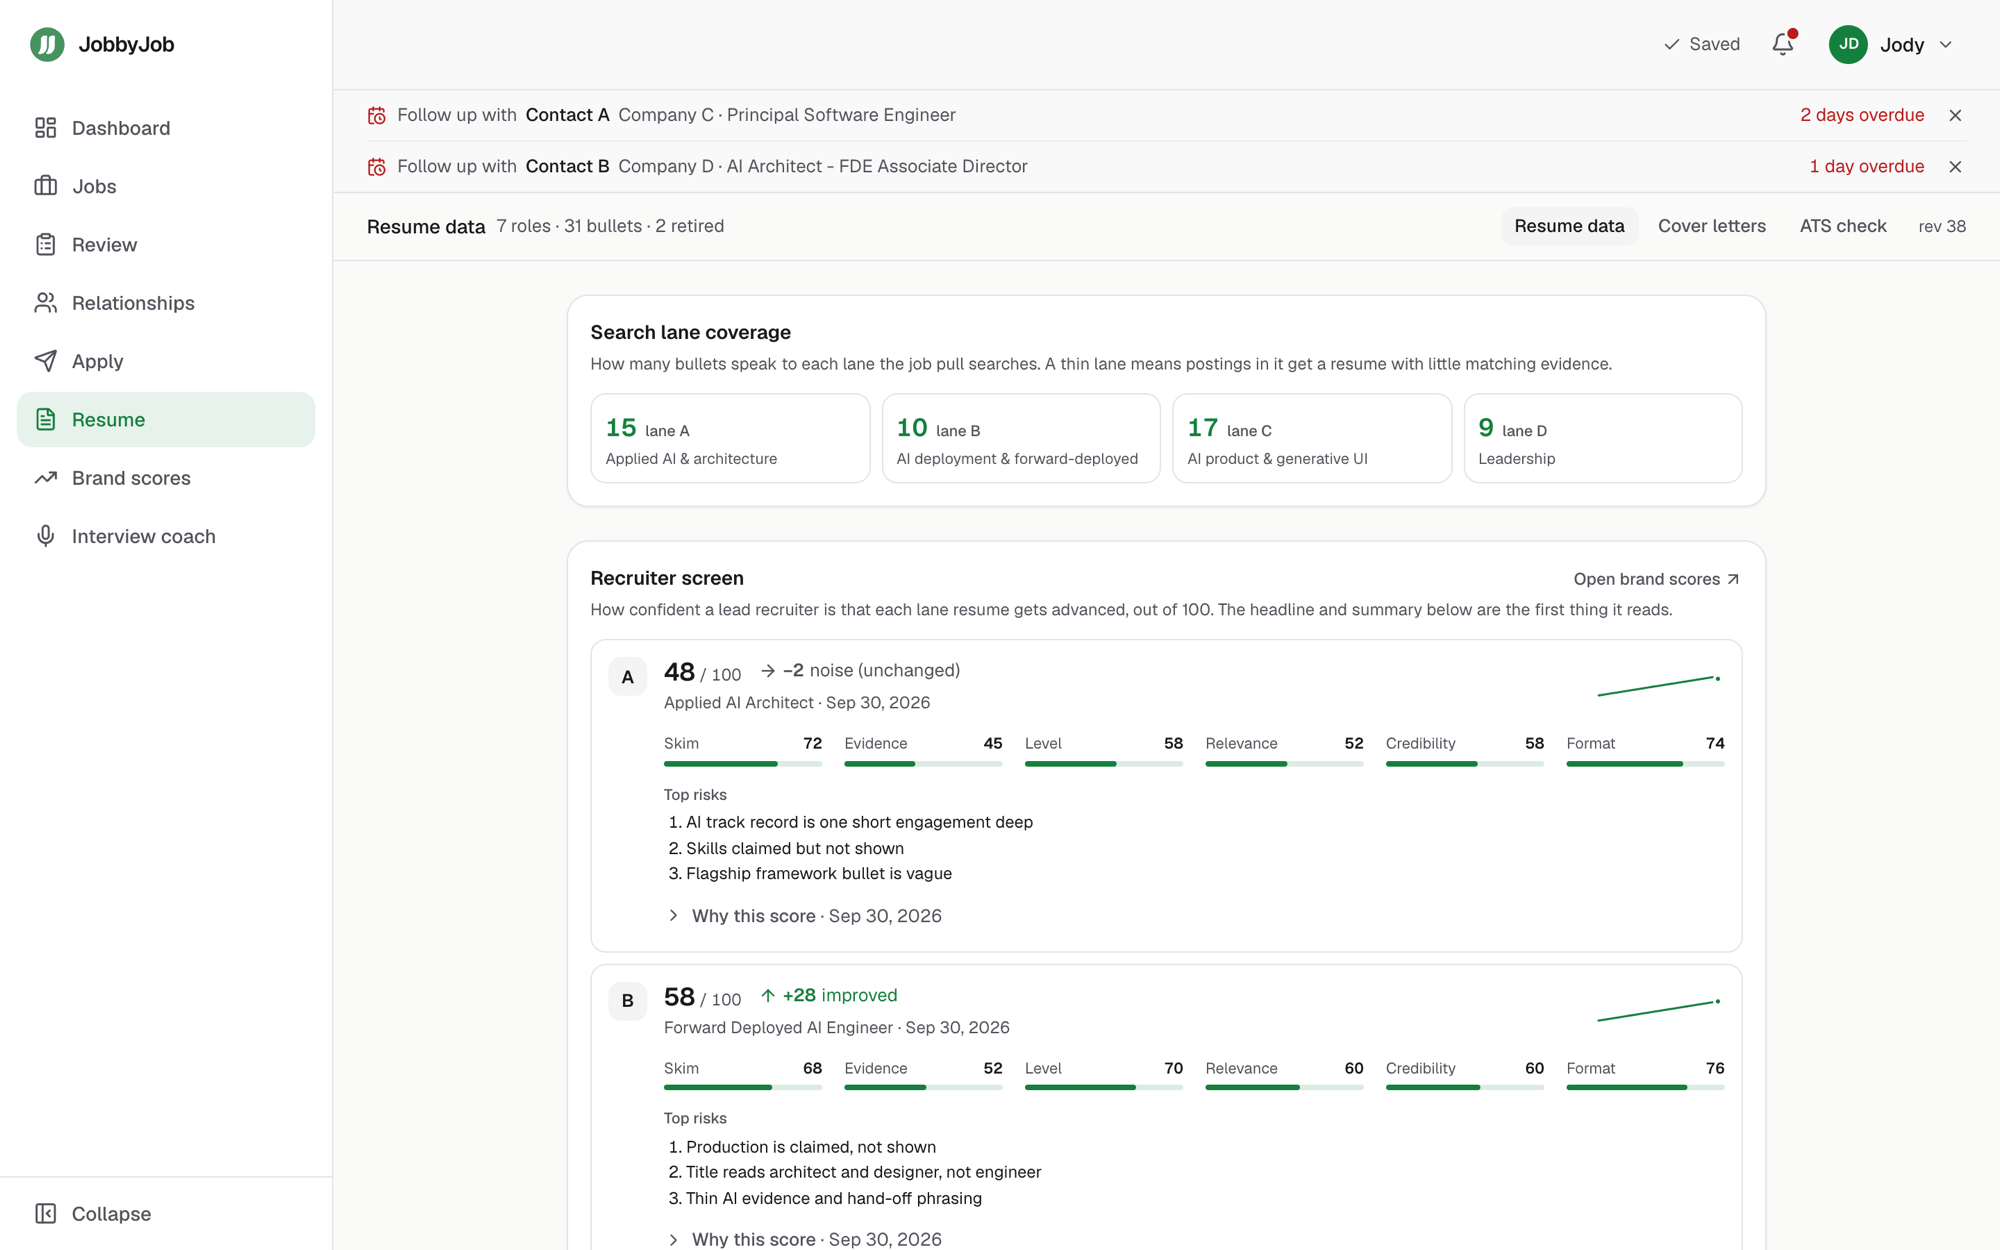
The lesson I didn’t expect was about attention. Between learning AI, keeping up with it, relearning fundamentals and building all of this, I let the basics slide. My LinkedIn profile went stale. I let agents maintain my resume and didn’t read it closely enough. An interviewer told me, “I found an issue in your resume.” When I went back, I found bullets describing my work in ways I never would have. I fixed the master record, set a cutover date and rebuilt every resume from it. The agents still assemble resumes, but only from bullets I’ve signed off on.
Automation scales whatever you give it, mistakes included. The review that matters most is on anything that carries your name.
Rules written in a prompt are suggestions. Rules written in code are rules. Almost every guardrail in this system exists because something went wrong without it. Each one is written down next to the incident that caused it.
Two months ago I wanted a list of my contacts. Now I have a live coach that knows my weak spots. I can send out 18 quality applications in a day. I still don’t have the job. But I understand agentic development from building it under real stakes, not from reading about it.
Built with Claude Code, Teable, one launchd job, 14 slash commands and a list of rules that each started as a mistake.
Company and people names in the screenshots are replaced with placeholders such as “Company A” and “Contact A”.